Vault: Making Unstructured Data Work for Investing
Day 1 · Oct 13 Day 1 digest · More from this day
Bridgewater built Vault, a governed 100-million-document platform for external and internal unstructured data, because frontier models fail on the open web — and the real prize is an always-on agent that captures what the firm learns back into the corpus.
Read the official edition ↗ A detailed reading edition with a searchable transcript.
- Bridgewater’s Vault holds more than 100 million documents, grows by thousands per day from 135 external sources, and ingests all internal writing — all aligned to the firm’s ontology with countries, concepts, markets, and time period.
- Humans and agents need different things from search: humans read about 300 words per minute and need precision; agents read about 30,000 words per minute, are less sensitive to precision, and drive 100-plus queries per second.
- A benchmark of about 200 hand-labeled examples, built in under a week, took precision at 10 from about 60% to 90–95% after five improvements that ended with agentic search.
- Metadata filtering forced a vector database change: TurboPuffer’s native filtering gives post-filter speed with near pre-filter recall.
- Adoption came from habit migration, not tool quality alone: broker email lists became saved searches, folders became saved collections, then the platform spread to chat, phone, Slack, the IDE, and a CLI for agents.
- The close: an “investor workbench” where an always-on agent proposes topics with summaries and exact evidence, and every human-agent collaboration is captured back into the Vault so the firm compounds.
Key lessons
Section titled “Key lessons”- Build for two consumers with opposite needs. Humans need precision and a high signal-to-noise ratio; a fast reader manages about 300 words a minute, and Bridgewater’s 300 users generate about 100 queries an hour. Agents are a different reader: less sensitive to precision (“If the data is there, they’ll find it”), consuming about 30,000 words a minute — 100 times faster — at 100-plus queries a second, with swarms into the thousands.
- Great data plus the right connectors makes agents useful. Asked how AI infrastructure investment affects the Korean won, an enterprise chat client on the open web found 15 resources, drew on one or two, leaned on a note from July 2026 when the question was asked in early October, and admitted it could not establish market consensus. Attached to Vault, the same query prompted the agent to scope to October 1–8, found 52 candidate documents, drew on seven, and returned a confident answer.
- Benchmark search before you fix it. The team collected about 200 questions, found the best documents by hand (including ones that looked helpful but were not), and finished in less than a week. The result confirmed the complaint — precision at 10 was about 60% — and gave a metric that five improvements eventually lifted to 90–95%.
- Production queries almost always carry conditions — as of a date, from a source, about an asset. Post-filtering a vector index is fast but loses recall; pre-filtering has recall but is slow. TurboPuffer’s native filtering looks only in the nearest clusters that contain matches and scores just those, giving post-filter speed with close to pre-filter recall — and it absorbed the agents’ 100-plus queries per second.
- You cannot drop a tool on investors’ desks and expect use. Researchers lived in broker email with subscribed lists and folder rules that worked and felt complete. Vault copied the habits: everything searchable, subscribed lists became saved searches, folders became saved collections. Only then did new habits open up — asking questions across all data, following dynamic topic feeds, handing collections to agents — which is when product-market fit arrived.
- Once the tool fits, deliver it everywhere: chat, a phone app, Slack, the IDE, and a CLI for the agents, “because agents love CLIs.”
- The platform compounds into products: the pocket analyst does hours of research in a few minutes for a few dollars; the researcher stretches that across days or weeks; custom models like the forecaster produce AI-generated macro predictions; and investment signals turn unstructured data into structured tradable strategies.
- The real prize is a proactive agent. The investor workbench keeps an agent always on, tracking what matters to each investor and surfacing topic cards with an agentic summary plus the exact evidence behind the recommendation; when the investor digs in, the collaboration’s results are captured automatically back into the Vault for the next turn.
Watch this session
Section titled “Watch this session”Figures
Section titled “Figures”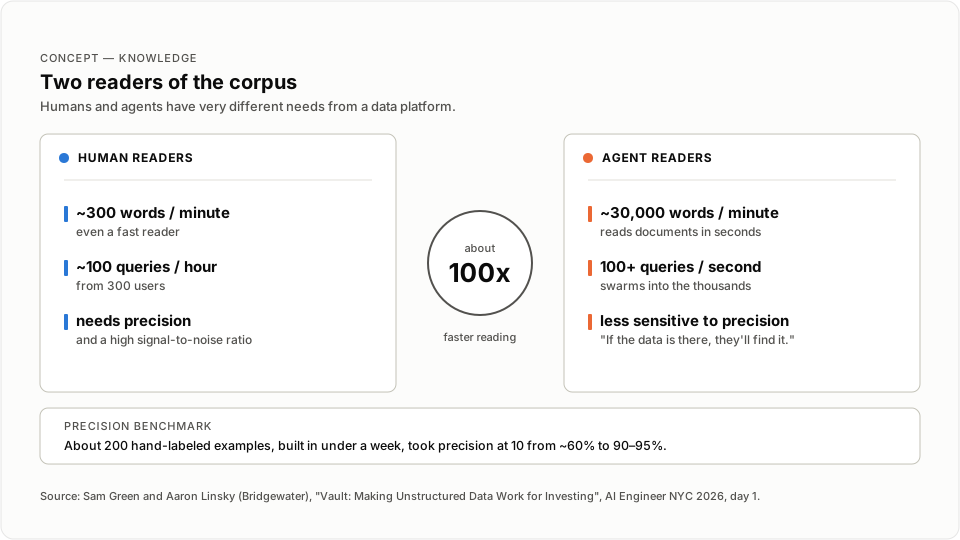
Bridgewater’s split between the two classes of reader.
Notable quotes
Section titled “Notable quotes”- “And what originally began as a set of if-then rules on a yellow legal pad evolved into a continuous compounding process with humans at the center, constantly looking for the next thing that’s changing in markets.” [00:16:06 | 9:03:57 AM]
- “Even a fast reader manages about 300 words a minute, and personally, I’m much slower.” [00:22:02 | 9:09:53 AM]
- “And that’s my second lesson that I want to share here, is that no matter how amazing the tools are, we can’t just drop them on our investors’ desks and expect them to be used.” [00:26:28 | 9:14:19 AM]
- “And so our question for you is, does your AI know what’s going on in the world, and does it remember what your firm has learned about it?” [00:30:51 | 9:18:43 AM] (“Because we are teaching ours too.” follows at [00:30:57 | 9:18:49 AM].)
Session narrative
Section titled “Session narrative”The first keynote of the day opens with a hand-off, not a talk. At 9:01:41 AM the MC introduces “two amazing folks from Bridgewater who are in the weeds of production AI every single day.” Slides are not ready, so the MC fills the delay by teasing the next session, welcoming Anthropic’s Belinda Neal and Keon Shahab to the room. Once the slides appear at 00:14:44, Sam Green takes over: he leads Applied AI at Bridgewater, and with Aaron Linsky he will share three lessons from building the Vault — humans and agents need different data platforms; the greatest impact comes when one tool serves both at once; and the real prize is making agents proactive participants rather than reactive tools.
Green grounds the talk in Bridgewater’s 50-year pursuit of encoding how markets and economies work, from if-then rules on a yellow legal pad, to time series models on carefully governed structured data, to AIA, the Artificial Investment Associate that puts a machine at the center of the process. Language models opened a wider world — news, research, transcripts, policy documents, and internal memos and debate — but that data needed the same cleaning, governance, and alignment as the structured store, and no vendor offered enough control. So Bridgewater built Vault: more than 100 million documents, thousands more each day from 135 external sources, plus all internal data, enriched with countries, concepts, markets, and time period. His demo makes the argument concrete. An enterprise chat client answering a question about AI infrastructure investment and the Korean won finds 15 web resources, uses one or two, leans on a July 2026 note in early October, and admits failure. The same query against Vault narrows to October 1–8, pulls 52 candidates, cites seven, and answers with confidence. His takeaway: “it takes great data and the right connectors to make agents impactful.”
Aaron Linsky then delivers the product engineering half, organized around five dimensions — recall, precision, filtering, entitlements, and scale — with deep dives on three. Precision: after the “heroic effort” of filling the Vault, the top complaint was “Vault search is bad,” so the team benchmarked it with about 200 hand-labeled examples in under a week, measured precision at 10 at about 60%, and shipped five improvements that reached 90–95% with agentic search. Filtering: production traces showed almost every query carried a condition, and classic pre- and post-filtering each failed one way, which drove the switch to TurboPuffer’s native filtering. Scale: 100 queries an hour from humans versus 100-plus per second from agents, which TurboPuffer also absorbed. His second lesson is about adoption — researchers lived in broker email, so Vault reproduced subscribed lists as saved searches and folders as saved collections, then expanded into chat, a phone app, Slack, the IDE, and a CLI. That base now powers the pocket analyst, the longer-horizon researcher, custom models like the forecaster, and investment signals built from unstructured data.
Green closes with the future: the investor workbench, where an always-on agent tracks what matters to each investor and presents topic cards carrying an agentic summary and the exact evidence, so the human can judge the recommendation, dig deeper, or ignore it. Every dig-in is captured automatically back into the Vault, which is how the platform compounds — the right evidence at the fingertips, and the synthesis of each human-agent collaboration returned to the corpus for the next turn. He ends at 9:18:43 AM with a question to the audience — “does your AI know what’s going on in the world, and does it remember what your firm has learned about it? Because we are teaching ours too” — an invitation to talk, and thanks, before applause hands the stage to the Anthropic keynote. One caveat on boundaries: the first minute of this segment is the MC’s hand-off, and the lines at 00:14:12–00:14:29 are the MC filling during the slide delay; the Bridgewater talk itself runs from 00:14:46 to 00:31:03.
Speaker details
Section titled “Speaker details”Sam Green - Team Lead, Applied AI, AIA Labs, Bridgewater Associates. Green leads Applied AI at AIA Labs, Bridgewater’s AI research and investment lab spearheaded by Co-CIO Greg Jensen, which builds AIA, an artificial investor that aims to meet or exceed expert human performance. He has been at Bridgewater since September 2017, previously researching systematic FX strategies and building quantitative models, and studied at Harvard University, where he was a Head Teaching Fellow for Computer Science 51. LinkedIn: https://www.linkedin.com/in/sa-muel-green
Aaron Linsky - Head of Product Engineering, Bridgewater. Linsky is Head of Engineering for Bridgewater’s Alpha Engine and a Partner of the firm, which he joined in 2008; he was previously the founding Chief Technology Officer of AIA Labs, where he built the technology platform behind AI-first investment research and strategies. He began at Bridgewater as a data analyst on the Equities team, helped migrate the research platform to the cloud, and led the redesign of the application stack for portfolio operations. He graduated magna cum laude from Princeton University with a degree in Operations Research and Financial Engineering. LinkedIn: https://www.linkedin.com/in/aaronlinsky
Full timestamped transcript
Section titled “Full timestamped transcript”[00:13:48 | 9:01:40 AM] Awesome.[00:13:50 | 9:01:41 AM] So we are going to hop into the first keynote of the day.[00:13:57 | 9:01:48 AM] We have two amazing folks from Bridgewater who are in the weeds of production AI every single day.[00:14:04 | 9:01:56 AM] So let's give it up for them.[00:14:06 | 9:01:58 AM] Welcome, guys.[00:14:12 | 9:02:04 AM] Coming up next, we're delighted to welcome two speakers from Anthropic.[00:14:18 | 9:02:09 AM] Please put your hands together for Belinda Neal, Managing Director of Financial Services, and Keon Shahab, Applied AI Architect.[00:14:29 | 9:02:21 AM] Just waiting for our slides.[00:14:44 | 9:02:36 AM] There we go.[00:14:46 | 9:02:38 AM] Good morning, everyone.[00:14:47 | 9:02:39 AM] I'm Sam Green, team lead for Applied AI at Bridgewater Associates, and this is my colleague Aaron Linsky.[00:14:55 | 9:02:46 AM] And today we're here to talk to you about the Vault, the data platform that we've built at Bridgewater to turn unstructured data into a first-class asset in our investment process.[00:15:05 | 9:02:57 AM] And as part of the talk this morning, we'd like to share three lessons that we've learned building the Vault.[00:15:11 | 9:03:02 AM] The first is that humans and agents have very different needs from a data platform, and so you have to build for those different needs separately.[00:15:21 | 9:03:12 AM] The second is that the greatest impact occurs when a single tool can meet both of these sets of needs at the same time.[00:15:27 | 9:03:19 AM] And the third is that the real prize is when you can build the foundations needed to make agents a proactive participant in your investment process or whatever you're doing with your tools.[00:15:39 | 9:03:30 AM] Instead of a reactive tool for your humans to use.[00:15:46 | 9:03:37 AM] Before I dive deeper into talking about the vault, I wanted to start with some background about Bridgewater.[00:15:51 | 9:03:43 AM] Over the last 50 years, Bridgewater has been in the constant pursuit of the world's best understanding of how markets and economies work, and turning that into a systematic encoding that we can use to stress test our logic over time.[00:16:06 | 9:03:57 AM] And what originally began as a set of if-then rules on a yellow legal pad evolved into a continuous compounding process with humans at the center, constantly looking for the next thing that's changing in markets.[00:16:18 | 9:04:10 AM] And more recently, we've been working on building AIA, the Artificial Investment Associate, which puts a machine at the center of this continuous process.[00:16:27 | 9:04:19 AM] Across all these phases of evolution, we've had a constant philosophy in mind, which is that we want to be constantly looking at how the world is changing and what's going on in the world, noticing what dynamics are not yet encoded in our understanding, and use that learning to improve and compound for the future.[00:16:49 | 9:04:40 AM] For most of Bridgewater's history, that meant building and overseeing time series models on structured data.[00:16:55 | 9:04:47 AM] And that structured data needed to be carefully built so that it could be safe for use in our research process and aligned to our internal ontology and world model so that we could get great leverage out of using the data that we had built.[00:17:10 | 9:05:01 AM] With the emergence of language models, we had a huge new opportunity to engage with a much wider world of data.[00:17:16 | 9:05:08 AM] You know, news and research, transcripts, policy documents, and all of the internal conversation that was previously just in the ether.[00:17:25 | 9:05:16 AM] So the internal memos and meeting transcripts and debate happening inside the firm.[00:17:30 | 9:05:21 AM] We quickly realized that all of that data needed the exact same treatment to be fit for purpose.[00:17:36 | 9:05:27 AM] It needed to be carefully cleaned, governed, and made ready for use in both point-in-time research questions today and also our systematic study over time.[00:17:47 | 9:05:39 AM] And when we looked out at the landscape of data vendors and data platform providers, there was nothing that provided us with all of the control that we needed to build and maintain our data advantage.[00:18:00 | 9:05:51 AM] And so we built the Vault, which is our repository of external and internal unstructured data, and the platform that indexes, organizes, and makes all of it ready for use by our human investors and agents.[00:18:15 | 9:06:06 AM] Today, the Vault has more than 100 million documents in it, with thousands more added every day, minute by minute, from 135 external sources and, again, growing all the time, as well as all of the data from inside of Bridgewater.[00:18:29 | 9:06:21 AM] And crucially, all that data is not just dumped on our investors' desks; it is carefully aligned to our internal ontology with enrichments like the countries, concepts, markets, and most importantly, time period discussed in the document.[00:18:48 | 9:06:39 AM] To bring this to life, I want to start with a quick motivating example.[00:18:51 | 9:06:43 AM] So what I did here is I asked a fairly basic representative investment question to an enterprise chat client.[00:19:00 | 9:06:51 AM] I asked, How is AI infrastructure investment impacting the Korean won, and do market participants expect this to continue?[00:19:07 | 9:06:59 AM] And as you're all, I'm sure, familiar with, the agent goes to the web and looks for resources it can draw on because I've explicitly asked it to go find other people's perspectives on the question.[00:19:21 | 9:07:12 AM] And you can see it zooms in and it finds 15 relevant-looking resources to draw on before it gives me back its answer.[00:19:30 | 9:07:22 AM] And when I zoomed in on the answer it gave back, a couple of things stood out to me.[00:19:34 | 9:07:25 AM] The first is that even though it found 15 relevant-looking sources, it only picked one or two to answer my question.[00:19:42 | 9:07:34 AM] And the second is down at the end of this response, where the agent itself acknowledges that it hasn't answered my question.[00:19:49 | 9:07:41 AM] It didn't find enough documents on the open web to establish a market consensus and meet the parameters that I laid out.[00:19:58 | 9:07:50 AM] When I double-clicked even further, the problem got even worse.[00:20:00 | 9:07:52 AM] One of the notes that it primarily drew on to answer my question was published way back in July of 2026, even though I asked this question and captured this answer just at the end of last week in early October.[00:20:16 | 9:08:08 AM] In the age of AI and in investing, three months is a massive amount of time.[00:20:22 | 9:08:13 AM] It's not even close to good enough to draw on this resource to answer my question.[00:20:28 | 9:08:20 AM] When I asked this exact same query attached to the vault, something totally different happens.[00:20:34 | 9:08:26 AM] The first is that the connection to the vault helps to prompt the agent that it should look for a specific period of time when answering my question.[00:20:41 | 9:08:32 AM] So it zooms in on October 1st to October 8th.[00:20:44 | 9:08:36 AM] It finds a much wider array of resources, 52 candidate documents that are relevant to the query over this specific period of time because of the vault's much more significant corpus of content that's relevant to investing questions.[00:20:59 | 9:08:50 AM] And when it ultimately answers my question, it draws on seven instead of only one or two and gives me back a rich answer that the agent is more confident is going to address my question.[00:21:12 | 9:09:03 AM] And so for us, this is the big lesson from building the vault to kind of motivate the talk today, which is that it takes great data and the right connectors to make agents impactful.[00:21:22 | 9:09:13 AM] And I'm going to hand it over to Aaron now to talk about some of the product engineering takeaways from building the vault.[00:21:27 | 9:09:18 AM] Thanks, Sam.[00:21:28 | 9:09:19 AM] So hi, I'm Aaron.[00:21:30 | 9:09:21 AM] I run product engineering at Bridgewater.[00:21:32 | 9:09:24 AM] I'm going to take us through a few of our learnings from building the vault over the past few years.[00:21:37 | 9:09:28 AM] I'm going to start with one that might seem obvious, but I still think it's worth saying, which is search is hard.[00:21:46 | 9:09:37 AM] But it gets even harder if we're designing for two different consumers.[00:21:50 | 9:09:41 AM] And in this case, we're designing for humans and agents.[00:21:52 | 9:09:44 AM] I'm going to go over the difference here, starting with us.[00:21:56 | 9:09:47 AM] So humans need precision and a high signal-to-noise ratio because we can only read so much.[00:22:02 | 9:09:53 AM] Even a fast reader manages about 300 words a minute, and personally, I'm much slower.[00:22:08 | 9:10:00 AM] Agents are a different kind of reader.[00:22:10 | 9:10:02 AM] They're far less sensitive to precision.[00:22:13 | 9:10:04 AM] If the data is there, they'll find it.[00:22:15 | 9:10:07 AM] And basically anything you hand to them will get attended to.[00:22:19 | 9:10:11 AM] They scale super quickly, and they consume about 100 times faster, 30,000 words per minute.[00:22:28 | 9:10:19 AM] And so we need to build Vault for both of these.[00:22:30 | 9:10:22 AM] And when we're thinking about the dimensions that matter, there are these five on the board: recall, precision, filtering, entitlements, and scale.[00:22:42 | 9:10:33 AM] Some of them matter to people, some matter more to agents, many to both.[00:22:46 | 9:10:38 AM] I'm going to go deep on three of these: precision for people, scale for agents, and then filtering for both.[00:22:54 | 9:10:45 AM] So, precision.[00:22:56 | 9:10:48 AM] Once we'd filled the vault, which was a heroic effort by our data and legal teams, recall was no longer a pressing issue.[00:23:05 | 9:10:56 AM] However, the number one complaint was, Vault search is bad.[00:23:09 | 9:11:01 AM] As the product owner, it's painful to hear that, but my response was, Let's benchmark it.[00:23:15 | 9:11:06 AM] And that's what we did.[00:23:16 | 9:11:08 AM] We collected questions and found the best documents by hand, including ones that looked helpful but weren't.[00:23:23 | 9:11:15 AM] In total, it was about 200 examples, and it took us less than a week.[00:23:27 | 9:11:18 AM] It was not fun or very glamorous, but it was very helpful.[00:23:32 | 9:11:23 AM] And after we ran it, it was very clear: search was bad.[00:23:36 | 9:11:27 AM] The key metric we were looking at is precision at 10, which is, of the top 10 results, how many are the right documents?[00:23:44 | 9:11:36 AM] And we were hitting about 60%.[00:23:47 | 9:11:38 AM] So the people were right, it was bad.[00:23:50 | 9:11:41 AM] But now we had a way to measure all of the improvements.[00:23:53 | 9:11:45 AM] And here on the board are five of them.[00:23:56 | 9:11:47 AM] And by the time we got done with agentic search, we were up in the 90, 95% recall at 10, or precision at 10.[00:24:04 | 9:11:55 AM] All right, so that was precision.[00:24:07 | 9:11:59 AM] Now on to filtering.[00:24:10 | 9:12:01 AM] Like anyone, we want the most relevant documents.[00:24:13 | 9:12:04 AM] But when we looked at the production traces, what we were seeing is that almost always there was some condition, either as of a certain date, or from a certain source, or about a specific asset.[00:24:25 | 9:12:17 AM] And all of that requires advanced filtering.[00:24:27 | 9:12:19 AM] And that's where we ran into our first major performance issue.[00:24:31 | 9:12:23 AM] So I'm going to quickly go through this, a little bit technical here.[00:24:37 | 9:12:28 AM] There's classically two ways to filter a vector database.[00:24:42 | 9:12:33 AM] Post-filtering will use that vector index first and then filter the top results by metadata.[00:24:47 | 9:12:38 AM] It's fast, but recall could be pretty low because the globally relevant results might not match your filters.[00:24:55 | 9:12:46 AM] On the other side, we have pre-filtering, where we'll filter first and then calculate distances for every one of those matches.[00:25:02 | 9:12:53 AM] The advantage there is that the recall is very good, but it can be very slow, and we needed something in between.[00:25:08 | 9:13:00 AM] So that's what led us to try and then ultimately switch to TurboPuffer.[00:25:12 | 9:13:03 AM] Their approach, which they call native filtering, looks only in the nearest clusters that contain matches and then scores just those.[00:25:19 | 9:13:10 AM] What you end up getting is something that's fast like post-filtering, but with close to the same recall as pre-filtering.[00:25:28 | 9:13:19 AM] And lastly, I'm going to talk about scale.[00:25:31 | 9:13:23 AM] Human scale for us is pretty pedestrian: 100 queries an hour.[00:25:34 | 9:13:26 AM] We have 300 users.[00:25:36 | 9:13:27 AM] They're going to search, you know, every so often.[00:25:38 | 9:13:30 AM] It takes our users minutes to read the docs that they're receiving.[00:25:42 | 9:13:34 AM] Agents, on the other hand, are a few orders of magnitude beyond that.[00:25:48 | 9:13:39 AM] Easily 100-plus queries a second, and agent swarms can hit thousands easily.[00:25:53 | 9:13:44 AM] And they obviously will read, as I said earlier, will read docs in seconds.[00:25:56 | 9:13:48 AM] So we need something that could scale as well.[00:25:59 | 9:13:51 AM] And again, TurboPuffer handled that easily too.[00:26:03 | 9:13:55 AM] So we were covering all five dimensions.[00:26:05 | 9:13:57 AM] I didn't talk about entitlements, but I'll be talking about that later today.[00:26:09 | 9:14:00 AM] But we covered it all.[00:26:10 | 9:14:02 AM] It unlocked new workflows, but it didn't change how our researchers worked.[00:26:16 | 9:14:07 AM] They still weren't coming to Vault every morning.[00:26:19 | 9:14:10 AM] And that's my second lesson that I want to share here, is that no matter how amazing the tools are, we can't just drop them on our investors' desks and expect them to be used.[00:26:28 | 9:14:19 AM] We need to migrate their old habits into a new form.[00:26:34 | 9:14:25 AM] And so we looked at what they were already doing.[00:26:37 | 9:14:29 AM] Many of them were living in email.[00:26:38 | 9:14:30 AM] The research came straight from the brokers.[00:26:41 | 9:14:32 AM] They had subscribed lists.[00:26:42 | 9:14:33 AM] They had rules that filtered everything into folders.[00:26:45 | 9:14:37 AM] It worked.[00:26:46 | 9:14:38 AM] It was familiar.[00:26:48 | 9:14:39 AM] And they knew that they weren't missing anything.[00:26:50 | 9:14:42 AM] So we had to build all of these features into the Vault.[00:26:54 | 9:14:45 AM] That's exactly what we did.[00:26:55 | 9:14:47 AM] Everything searchable.[00:26:56 | 9:14:48 AM] The subscribed lists became saved searches, and folders became saved collections.[00:27:02 | 9:14:53 AM] It's the same habits, just a new home.[00:27:04 | 9:14:56 AM] And once we had them there, we can open up new habits.[00:27:07 | 9:14:59 AM] So they can ask questions across all the data, as Sam showed.[00:27:12 | 9:15:03 AM] They can follow dynamic feeds by topic, and they can hand those collections over to their agents to take further action.[00:27:18 | 9:15:10 AM] And that's when we clearly had product-market fit.[00:27:22 | 9:15:14 AM] And once we had that fit, the users wanted it everywhere, so we put it in chat.[00:27:26 | 9:15:18 AM] We made a phone app.[00:27:28 | 9:15:19 AM] It's in Slack and their IDE, and of course, we availed all of that to the agents as well, including a CLI because agents love CLIs.[00:27:37 | 9:15:29 AM] And so the main question here is, okay, so what does this enable?[00:27:40 | 9:15:32 AM] Sam is going to talk about what we're building right now, but first and foremost, it's helping us to move around that research circle faster.[00:27:49 | 9:15:41 AM] With our pocket analyst, which is our first AI analyst, it can do hours of research in just a few minutes for a few dollars, and that's relying on the vault.[00:28:01 | 9:15:52 AM] And then we're expanding that now with the researcher, which is the next generation.[00:28:04 | 9:15:56 AM] It's the same idea stretched across days or weeks.[00:28:09 | 9:16:01 AM] We're also able to train custom models to more intelligently reason over the vault's data and use those together with other foundation models to feed systematic decision-making processes.[00:28:20 | 9:16:11 AM] The forecaster is our first one, which produces AI-generated macro-relevant predictions.[00:28:26 | 9:16:18 AM] And then we also have built investment signals from the vault, turning unstructured data into structured tradable strategies.[00:28:35 | 9:16:26 AM] Now I'll hand it to Sam to take us through Vault's latest capability.[00:28:42 | 9:16:33 AM] So, like I alluded to at the beginning of the talk, the real prize is when you can take agents from a reactive resource that can be ready to answer a human's question and instead make them proactive participants, helping to steer your high-value professionals towards the most important areas for their attention.[00:29:02 | 9:16:53 AM] And the way that we're solving that problem is in an experience we're calling the investor workbench, where the Agent is always on, tracking what's important to that investor and presenting them with the areas that are most in need of their attention.[00:29:17 | 9:17:08 AM] It looks like an experience like this that relies on the vault, where a topic is proposed and several pieces of information are presented to the investor to decide whether they should dig deeper or ignore that topic entirely.[00:29:30 | 9:17:21 AM] You can see here the card that an investor sees in order to decide whether to dig in deeper into the same AI impact on currencies question that we looked at earlier in the talk.[00:29:40 | 9:17:31 AM] And the investor receives everything they need: an agentic summary if they want a quick scan across the agent's findings.[00:29:47 | 9:17:39 AM] They also get the exact evidence that the agent was drawing on so that they can assess for themselves what was leading to this recommendation.[00:29:56 | 9:17:47 AM] And if they choose to dig deeper, they have a direct connection to the research output from the analytical tools that Aaron was just...[00:30:02 | 9:17:53 AM] Aaron was just describing.[00:30:02 | 9:17:53 AM] And when they dig deeper alongside the agent to look at the dynamics driving this question, the learnings are automatically captured.[00:30:12 | 9:18:04 AM] The results of their collaboration are automatically captured back in the vault.[00:30:19 | 9:18:11 AM] And so this, for us, is the key lesson.[00:30:21 | 9:18:12 AM] The vault enables compounding because it provides the right evidence, the right internal and external information at the fingertips of our investors and agents, and it automatically captures the synthesis that they generate and puts it back in the corpus for the next turn.[00:30:38 | 9:18:29 AM] And that makes us go around the circle faster and better.[00:30:41 | 9:18:33 AM] And so when we think back to the question we began with, what it takes to make an agent work is the right context and the right understanding of what's going on in your world.[00:30:51 | 9:18:43 AM] And so our question for you is, does your AI know what's going on in the world, and does it remember what your firm has learned about it?[00:30:57 | 9:18:49 AM] Because we are teaching ours too.[00:30:59 | 9:18:51 AM] And if these sound like an exciting challenge, we'd love to talk.[00:31:03 | 9:18:54 AM] Thank you.