What does an AI engineer do?
Day 1 · Oct 13 Day 1 digest · More from this day
Aparna Dhinakaran (Arize AI) argues the AI engineer’s job has shifted from writing AI features to building the always-on loop — agents, evals, and telemetry — that writes, reviews, and improves those features, illustrated by Arize’s Signal agent.
Read the official edition ↗ A detailed reading edition with a searchable transcript.
- The AI engineer’s job is “no longer to just write the feature” — it is to build the loop (build, eval, ship, monitor, improve) that does each of those steps.
- She cited a weekend tweet from “Kripati” (as transcribed) on the adoption funnel: 6 billion-plus users have touched an LLM, 1 to 2 billion are casual free-tier users, 20 million are professionals, and only about 5,000 frontier users run thousands of agents at once.
- Arize built Signal, an always-on agent that reads traces, identifies issues from telemetry, and can open a fix or PR when it has repo access.
- Signal runs in a sandbox reached only through a single proxy, saves issues and learned skills to memory, tears down credentials after each run, and resumes from the failed step if the sandbox or harness fails.
- Writing evals aligned with human judgment is where AI engineers should spend their time — including “evaluate the evaluators” with golden truth datasets before shipping a new evaluator.
- Close: trace everything, including the coding agents (Claude Code, Cursor, Codex) behind your agents, because AI engineers are the role that closes the gap between the labs and businesses.
Key lessons
Section titled “Key lessons”- Build the loop, not the feature. The role has moved from writing an AI feature, to building the system that writes it: agents do code reviews, evals review non-deterministic tasks, and agents read observability data to find patterns instead of humans reading dashboards.
- Locate yourself on the adoption funnel and climb it. Per the tweet she cited: 6 billion-plus users touched an LLM, 1 to 2 billion are casual free-tier users, 20 million professionals cut week-long work to days, and roughly 5,000 frontier users run thousands of agents at once. The roadmap question is how everyone becomes one of those 5,000 within a couple of years.
- Rising abstraction is the longer trend. Engineers went from writing high-level languages, to copy-pasting code, to local agents, to cloud agents, and now toward running teams or factories of agents — a decades-long shift that accelerated in the last couple of years.
- Design always-on agents around triggers, sandboxes, and memory. Signal triggers on a configurable cadence (every 3 or 6 hours it pulls the last batch of traces), on events (Slack messages, user complaints), or on metric thresholds. Each run loads trace context, third-party telemetry (APM logs and metrics), repo access, and keys into a sandbox whose only way in or out is a single proxy, with everything inside traced.
- Be explicit about what persists and what is destroyed after a run. Issues and any learned skills are saved to memory and the repo so the next run does not start from zero; the sandbox is torn down and credentials and repo access are removed. Durability means a failed sandbox or harness resumes from the failed step, with state saved outside the sandbox.
- Stay model- and harness-agnostic to trade cost against quality. Signal started with Claude Code and now supports Cursor and Codex, with a goal of supporting open-source harnesses; within Claude Code you can pick any model in the Anthropic family. Swapping models is how Arize evaluates agent quality and controls cost while keeping the rigor of detected issues.
- Evaluate the evaluators. Before shipping a new evaluator, Arize builds golden truth datasets, runs evals, verifies them against human output, and only ships once the judge agrees with the human. The same evals run offline (pre-ship testing) and online (on production telemetry).
- Trace the factory, not just the product. Tracing everything now means tracing the coding agents behind the agents — Claude Code, Cursor, Codex — so you can understand what happened in your factory of agents, then feed that telemetry back to the agents that surface problems.
Watch this session
Section titled “Watch this session”Figures
Section titled “Figures”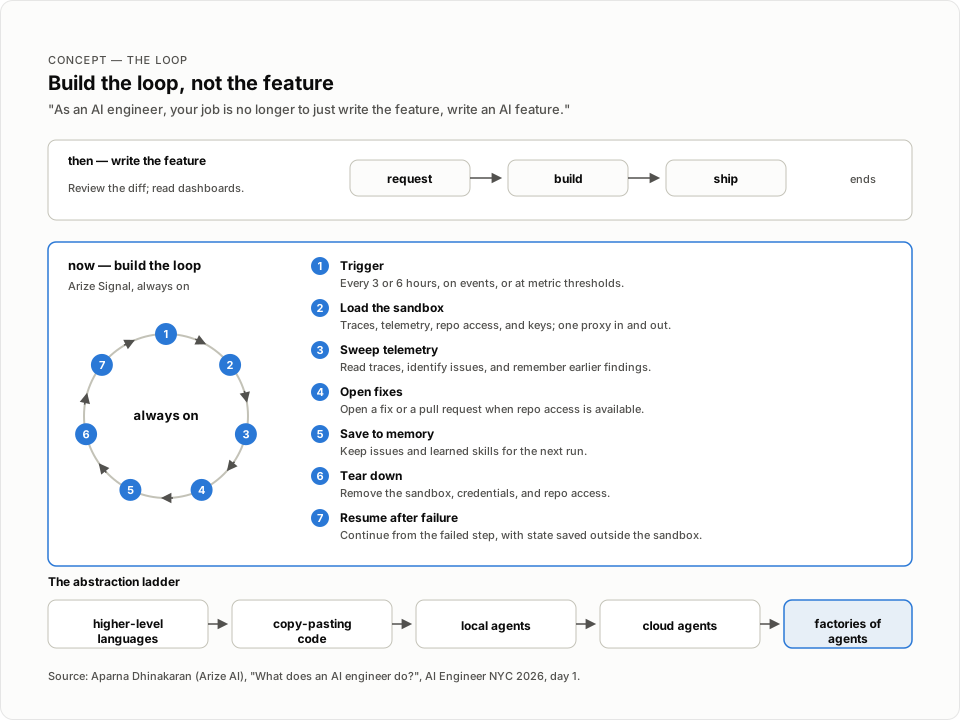
The always-on loop versus the linear feature pipeline.
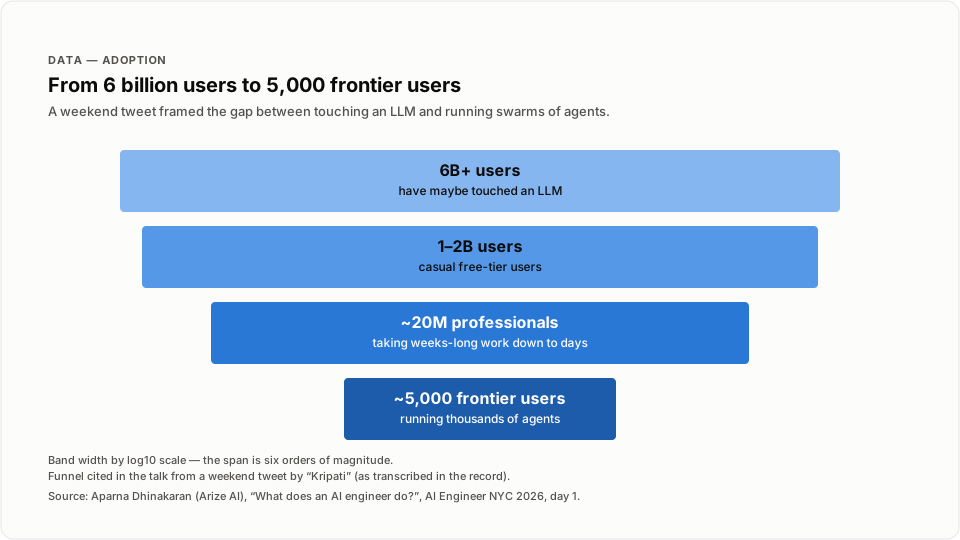
The usage pyramid the talk opened with, from touched to frontier.
Notable quotes
Section titled “Notable quotes”- “As an AI engineer, your job is no longer to just write the feature, write an AI feature.” — Aparna Dhinakaran [01:29:49 | 10:17:40 AM]
- “It’s about how do you build the loop to write that feature.” — Aparna Dhinakaran [01:29:53 | 10:17:44 AM]
- “It’s not even about humans consuming it and agents kind of taking on the task, but it really is how do you set up your telemetry data so that agents are the primary consumers of that data.” — Aparna Dhinakaran [01:32:15 | 10:20:06 AM]
- “But AI engineers are kind of the role to close that gap.” — Aparna Dhinakaran [01:41:56 | 10:29:48 AM]
Session narrative
Section titled “Session narrative”The segment opens at 10:14:49 AM with the host’s voice-over framing the agenda’s thesis — as AI takes on more of the building, defining success becomes the essential skill — and introducing Aparna Dhinakaran, co-founder and chief product officer at Arize AI. (The agenda slot listed 10:12am; the livestream segment starts with this introduction, and Aparna takes the mic at about 10:15:17 AM.) She opens by revisiting the question the conference is named for: what does an AI engineer do, a definition she says changes every year.
The setup is a tweet posted that weekend by “Kripati” (as the transcript renders it) describing a growing gap: 6 billion-plus people have touched an LLM, 1 to 2 billion are casual free-tier users, 20 million are professionals, and only about 5,000 frontier-lab users run thousands of always-on agents at once. She places this in a decades-long rise of abstraction — from writing higher-level languages to copy-pasting code, to local agents, to cloud agents, to factories of agents — and states her core claim: the AI engineer no longer writes the feature but builds the loop that writes, reviews, monitors, and improves it.
The middle of the talk is a build walkthrough of Arize Signal, the productized version of that loop. Signal reads traces on a configurable cadence (or event and metric triggers), identifies issues, keeps memory of previously seen issues, and can open a PR when it has repo access. She details the run architecture: context, third-party telemetry, repo access, and keys are placed in a sandbox; a single proxy is the only way in or out; everything inside is traced; outputs and learned skills persist to memory while the sandbox, credentials, and repo access are torn down. Durability is deliberate — a failed sandbox or harness resumes from the failed step using state saved outside the sandbox. Signal is harness-agnostic (Claude Code, Cursor, Codex today, open-source harnesses planned) and model-agnostic within the Anthropic family, which doubles as a cost-versus-quality lever.
The close returns to the role. Writing evals aligned with human judgment is where AI engineers should now spend their time: evals run on Signal’s PRs, and Arize “evaluates the evaluators” against golden truth datasets before shipping a new evaluator, then reuses those evals online against production telemetry. She ends by tying the loop together — collect data, eval it, run agents on it, find the gaps, improve — and by naming the gap between labs and messy enterprise data that AI engineers exist to close, inviting listeners to the Arize booth to see Signal. The stream cuts at 10:30:34 AM with the house announcement that the program has finished its run.
Speaker details
Section titled “Speaker details”Aparna Dhinakaran - Co-Founder & Chief Product Officer, Arize AI. She co-founded Arize AI in 2020, a pioneer in AI and agent observability and evaluation, and builds tools for understanding AI behavior and turning model and agent failures into engineering improvements. Previously she was a machine learning engineer and leader at Uber, where she built core ML infrastructure platforms including Michelangelo, and she also worked at Apple and TubeMogul (acquired by Adobe); she holds a BS in EECS from UC Berkeley, is a Forbes 30 Under 30 honoree, and Dynatrace completed its acquisition of Arize AI on October 1, 2026. Links: LinkedIn, X/Twitter.
Full timestamped transcript
Section titled “Full timestamped transcript”[01:26:57 | 10:14:49 AM] As AI takes on more of the building, what does it mean to be an engineer?[01:27:03 | 10:14:54 AM] Here to explore why defining success may become the essential skill, please welcome Aparna Dhinakaran, co-founder and chief product officer at Arize AI.[01:27:25 | 10:15:17 AM] Hey, New York.[01:27:27 | 10:15:18 AM] Awesome.[01:27:28 | 10:15:19 AM] Well, welcome to AI Engineer.[01:27:31 | 10:15:23 AM] Thought, given we're at AI Engineer New York, we'd kind of revisit the question of what does an AI engineer do?[01:27:38 | 10:15:30 AM] I feel like every year we have an idea of what an AI engineer does, and that definition kind of changes.[01:27:45 | 10:15:37 AM] And as I was putting this talk together, it was super timely because Kripati actually just tweeted something this weekend where he kind of talks about this growing gap.[01:27:57 | 10:15:49 AM] Between basically folks at the frontier who are running thousands of agents and swarms of always-on agents.[01:28:04 | 10:15:56 AM] And he really kind of drops this funnel where 6 billion-plus users have maybe touched or interfaced with an LLM, 1 to 2 billion are maybe like casual free-tier users, 20 million are professionals who have maybe started using it for more, taking some piece of work that would have taken weeks down to days.[01:28:26 | 10:16:17 AM] But really those at the frontier labs are, which is a super small percentage, it's like 5,000 users, are the ones who are running thousands and thousands of agents at once.[01:28:40 | 10:16:32 AM] And as I look at this, it really is, I mean, he's kind of dropped a bit of the funnel.[01:28:44 | 10:16:36 AM] I mean, the first question anyone looks at this is that, where am I on this?[01:28:48 | 10:16:40 AM] And, you know, he's kind of drawn out a bit of a roadmap of how does everyone get to, in the next couple of years, one of those 5,000 users who are running thousands of agents.[01:29:00 | 10:16:52 AM] And this has been happening, I'd say, for a couple of decades now, where the abstraction layer has gotten higher and higher.[01:29:06 | 10:16:58 AM] I mean, definitely faster in the last couple of years, but we've gone from engineers writing higher-level abstraction languages to, I mean, just copy-pasting code, using local agents, to using cloud agents, to really the expectation now is how do all of us start running a team of agents or factories of agents internally and build toward that.[01:29:33 | 10:17:25 AM] And what this has led to is essentially what is the then and now of what an AI engineer is.[01:29:38 | 10:17:30 AM] And this is a bit, I think, of a roadmap for some, but I think internally this is what we've already started to kind of push towards.[01:29:49 | 10:17:40 AM] As an AI engineer, your job is no longer to just write the feature, write an AI feature.[01:29:53 | 10:17:44 AM] It's about how do you build the loop to write that feature.[01:29:57 | 10:17:48 AM] It's no longer about— You know, just reading the diff and actually do.[01:30:02 | 10:17:53 AM] Actually, doing code review, it's actually how do you set up systems and agents to do the code reviews, and how do you write evals to actually do the non-deterministic, to review those non-deterministic tasks.[01:30:14 | 10:18:05 AM] It's actually no longer even about just setting up metrics and software kind of telemetry, but it's actually how do you have agents go through and read the observability data, and have agents actually consume that telemetry to find patterns.[01:30:28 | 10:18:20 AM] And so this loop that we've kind of been talking about, which is the build, eval, ship, you monitor, you improve it.[01:30:35 | 10:18:26 AM] Well, the AI engineer is now actually responsible not just for doing each of those steps, but how do you build the loop that actually does each of those steps.[01:30:45 | 10:18:37 AM] And at Arize, one of the things we've rolled out in our product, and I'm going to talk about a bit of what we've learned in building this, is we built Signal to actually run this loop for AI engineers.[01:30:56 | 10:18:47 AM] What Signal does is that Signal actually looks at all of the traces, it reads the telemetry, it identifies patterns in that telemetry, and it can actually put up a fix or a PR if it has access to the repo.[01:31:11 | 10:19:02 AM] And Signal is an always-on agent.[01:31:15 | 10:19:06 AM] So this is an example of how Signal starts, but it actually starts off by just reading the traces.[01:31:21 | 10:19:13 AM] Super simple example, but it goes through, reads, and all of this is configurable, but a certain volume of traces that came in in some cadence, it reads it, and then the goal is to actually identify issues from that telemetry data.[01:31:37 | 10:19:29 AM] It has to keep track of issues that it's previously seen.[01:31:41 | 10:19:32 AM] So we have to consider the memory of, did it see something before that it thought was an issue?[01:31:47 | 10:19:39 AM] Did something seem like an issue, but it wasn't actually captured, and now as it collects more data, it actually thinks it's much more of a critical issue.[01:31:55 | 10:19:47 AM] And so Signal actually starts off by reading the traces to identify problems.[01:32:01 | 10:19:52 AM] And so one of the first things that we realized was that the future of who's actually consuming telemetry data has really changed.[01:32:10 | 10:20:02 AM] It's no longer about humans consuming telemetry data.[01:32:15 | 10:20:06 AM] It's not even about humans consuming it and agents kind of taking on the task, but it really is how do you set up your telemetry data so that agents are the primary consumers of that data.[01:32:26 | 10:20:17 AM] And what that does is that that observability data can become the trigger for actually running and triggering these always-on agents.[01:32:35 | 10:20:26 AM] And so the first thing that, if you're building a team of a factory of really always-on agents, is what triggers these agents to wake up or start.[01:32:44 | 10:20:36 AM] And there can be a variety of triggers.[01:32:47 | 10:20:38 AM] For Signal, for us, it's configurable to run on an ongoing cadence, so every three hours, six hours, go pull the last X amount of traces, read them, identify problems.[01:33:00 | 10:20:51 AM] It can also be triggered by events, so Slack messages, some user complains about something.[01:33:08 | 10:20:59 AM] It can be a metric-based trigger, but these are essentially triggers to kick up the agent actually starting.[01:33:16 | 10:21:08 AM] Once the agent actually starts, we have to spend some time figuring out, well, what does an agent run actually look like?[01:33:22 | 10:21:14 AM] For us, we actually pull in all of the context of the traces, any additional third-party data, so we allow collecting to APM logs, APM metrics, but all of the third-party telemetry data that we want to pull in, access to the repo, access to the actual The access to any keys that are needed to actually run this agent, but all of this information is put inside of a sandbox.[01:33:54 | 10:21:46 AM] And this is actually what's started up every time the agent wakes up.[01:34:00 | 10:21:51 AM] And so the agent's triggered, we build a sandbox, we put everything that we need inside of that sandbox.[01:34:05 | 10:21:56 AM] There's a proxy.[01:34:05 | 10:21:57 AM] The only way to get information in and out of the sandbox is by this single proxy.[01:34:10 | 10:22:01 AM] And everything that happens inside of that sandbox is actually already getting traced.[01:34:15 | 10:22:06 AM] And every output, so the issues that are generated and created are all getting saved to some kind of memory.[01:34:23 | 10:22:14 AM] And so this happens every single time the agent actually runs.[01:34:26 | 10:22:18 AM] Every time the agent finishes running, so it's sweeped through all of the traces, it either found something or it didn't.[01:34:35 | 10:22:26 AM] There's what actually stays and what actually gets thrown away.[01:34:39 | 10:22:31 AM] What stays is that if it found any issues, all of the output is actually saved off in some kind of memory so that the next time an agent gets spun up, it doesn't have to start from ground zero.[01:34:49 | 10:22:41 AM] It has a history of what are the issues that it actually found.[01:34:54 | 10:22:46 AM] The agents are traced, so all of the telemetry data of what the agent called, if it actually put up a PR, all of those things are actually traced.[01:35:05 | 10:22:56 AM] And any skills that it may have learned while actually doing a run can also get saved to the actual repo.[01:35:11 | 10:23:03 AM] But the things that go away is the sandbox gets torn down, any credentials obviously get removed, the repo access is removed.[01:35:20 | 10:23:11 AM] And so all of the stuff that doesn't need to be saved kind of gets torn down after the run of Signal.[01:35:28 | 10:23:20 AM] And we've designed Signal in a way to actually keep this agent durable.[01:35:32 | 10:23:24 AM] So that means that either if the sandbox fails or if the harness fails, then it shouldn't have to start everything from scratch in the middle of the run.[01:35:44 | 10:23:35 AM] It should actually just be able to pick up from the step that it failed, and all of the state, so-called, is kind of saved off in kind of a memory outside of the sandbox.[01:35:56 | 10:23:47 AM] And so we've designed this to actually be a very durable agent so that if it fails, it can spin it back up.[01:36:05 | 10:23:56 AM] You can launch a new sandbox, launch a new harness to kind of pick back up where it started.[01:36:09 | 10:24:01 AM] So all of this is essentially the underpinnings of how we built Signal to run every single run.[01:36:16 | 10:24:07 AM] Agent gets triggered, agent gets started, loaded with all the context, the evidence.[01:36:20 | 10:24:12 AM] It sweeps through the telemetry data.[01:36:22 | 10:24:13 AM] It either finds something or it doesn't.[01:36:24 | 10:24:15 AM] All of that gets saved to memory.[01:36:26 | 10:24:17 AM] If something fails in the middle, the agent can get reset up.[01:36:29 | 10:24:21 AM] And we built Signal to also be, you know, agnostic of the model or the harness.[01:36:35 | 10:24:26 AM] So today's Signal supports not just Claude Code, which is what we started with, but it also supports Cursor and Codex.[01:36:40 | 10:24:32 AM] And the goal is to actually support all of the major, even the open source harnesses out there.[01:36:47 | 10:24:38 AM] And Signal actually also supports multiple, will support kind of multiple models.[01:36:54 | 10:24:46 AM] So even if you're using Claude Code, you can pick any of the models inside the Anthropic family.[01:37:01 | 10:24:53 AM] And this is really important to us because, one, it's an awesome way for us to evaluate the quality of the agent every time we spin it up.[01:37:11 | 10:25:02 AM] It helps us control costs so we can see, you know, as we use more powerful models.[01:37:16 | 10:25:08 AM] The better quality maybe the PRs are, but can we reduce the quality of the, you know, can we reduce the cost and actually still maintain the rigor and maintain the quality of issues that are actually detected by Signal?[01:37:30 | 10:25:21 AM] So this is something we deeply thought about from first principles when we were designing Signal.[01:37:35 | 10:25:27 AM] And this is actually a pretty good segue into what does an AI engineer need to do?[01:37:41 | 10:25:32 AM] Well, an AI engineer really needs to kind of learn how to write evals.[01:37:45 | 10:25:37 AM] And so we actually, every time Signal runs, Signal finds an issue, it puts up a PR.[01:37:50 | 10:25:42 AM] Well, there's evals that are run on top of the agent to test that PR.[01:37:55 | 10:25:47 AM] And an eval can be as simple as, you know, testing something as part of your development workflow.[01:38:02 | 10:25:53 AM] You have a dataset.[01:38:03 | 10:25:55 AM] It can be a simple prompt with outputs that you're testing to make sure that there's no regressions.[01:38:11 | 10:26:02 AM] But these evals can also, they need to be kind of aligned with human judgment.[01:38:17 | 10:26:08 AM] And I'd argue that this is actually probably where an AI engineer should be spending a lot of their time as they're building this system to actually run the loop.[01:38:26 | 10:26:17 AM] They should be actually spending time looking at the traces with their agents, identifying what the common errors are.[01:38:34 | 10:26:25 AM] And there's a lot of skills.[01:38:35 | 10:26:26 AM] I think I was hearing Lance yesterday talk about the Claude skill to build evals.[01:38:39 | 10:26:30 AM] We have a skill with Arize Evaluator to actually help you build and write evals, as well as align those evals with the human judgment.[01:38:48 | 10:26:40 AM] But this is probably where the shift to defining what is good becomes really, really important for an AI engineer to actually do.[01:38:58 | 10:26:49 AM] And for a lot of teams I think we speak with and we work with, their question becomes, well, how do I trust the evaluator?[01:39:04 | 10:26:56 AM] And do I really trust that the eval is, you know, is going to catch, or, you know, how do I trust that it's as good as my judgment?[01:39:16 | 10:27:08 AM] And I'd say what we spend a lot of our own time doing for our own products is that we actually evaluate the evaluators.[01:39:24 | 10:27:15 AM] We spend a decent amount of time on actually building.[01:39:29 | 10:27:20 AM] These data sets, golden truth data sets, we run evals, verify them against the human output, and then try to align to make sure that the judge actually agrees with the human and they're in agreement before we actually ship out a new evaluator.[01:39:46 | 10:27:38 AM] And these evals can then be used both in an offline testing as well as in an online testing manner.[01:39:54 | 10:27:45 AM] And this is probably what I would say as an AI engineer is more and more of what the job.[01:40:00 | 10:27:51 AM] The job is becoming.[01:40:00 | 10:27:51 AM] And so what I'm going to leave you guys with is, as an AI engineer, you've built this agent.[01:40:09 | 10:28:00 AM] You've built this agent to actually run, be always on.[01:40:12 | 10:28:04 AM] You run evals before you actually ship it into production.[01:40:17 | 10:28:09 AM] You can ship it, and then once it goes into production, the goal is to actually trace everything.[01:40:23 | 10:28:15 AM] And tracing everything now means not just tracing the agents, but also tracing the coding agents behind the agents that built this.[01:40:31 | 10:28:23 AM] So you can trace Cloud Code, you can trace Cursor, you can trace Codex, but all of these coding agents can be traced so you can understand what happened in the factory of agents that you all are building.[01:40:46 | 10:28:38 AM] And then these agents, all the traces can then also be evaluated online.[01:40:51 | 10:28:43 AM] So there's an offline evaluation when you're actually testing what a new change is, but as it goes into production, these become your online evals that you're running on top of the telemetry data.[01:41:04 | 10:28:56 AM] This for us ends up becoming the new data that then gets pulled back into the agents to read the telemetry data, the evals, and surface up kind of problems inside of the traces.[01:41:18 | 10:29:09 AM] So the system really becomes, how do you go from collect data, eval that data, run agents on top of it so that you can find problems and figure out where the gaps are to actually improve your systems.[01:41:33 | 10:29:24 AM] So if I go back to kind of the question that we started this whole thing with, it's what does an AI engineer do?[01:41:39 | 10:29:31 AM] I mean, the gap between, I think there's a pretty big gap between what's happening in the labs today and what's happening with a lot of businesses.[01:41:48 | 10:29:39 AM] And some of it could just be the data inside of businesses are a lot more messy than what is very constrained and testable inside of a lab.[01:41:56 | 10:29:48 AM] But AI engineers are kind of the role to close that gap.[01:42:01 | 10:29:52 AM] And I think it really starts with tracing everything, tracing the agents you're actually building, running evals, so being able to learn how to test these products that we're really building.[01:42:12 | 10:30:03 AM] And then how do you build a system so that agents can actually improve from the telemetry that's actually being collected, so that you're no longer just building individual features, but you're actually building the system to improve your products.[01:42:28 | 10:30:19 AM] If you want to learn more, come check out, we have a booth.[01:42:31 | 10:30:22 AM] You can check out Signal, learn more.[01:42:33 | 10:30:25 AM] But thank you so much for listening to us.[01:42:43 | 10:30:34 AM] The current program has finished its run.