Shipping like a startup, regulated like a bank
Day 1 · Oct 13 Day 1 digest · More from this day
Revolut’s David Abitbol explains how self-hosting GLM on 56 dedicated B200 GPUs cut the bank’s token bill to one-tenth, lifted engineering lead time 70%, and still passed EU bank compliance through sandboxing and human-in-the-loop controls.
Read the official edition ↗ A detailed reading edition with a searchable transcript.
- Revolut, an 80-million-customer digital bank in Europe, self-hosts the open-source GLM-4.3 model (800 billion parameters) on roughly 56 B200 GPUs to serve about 2,000 engineers.
- Self-hosting brought the blended token cost to 30 cents per million, about one-tenth of the previous Anthropic and OpenAI invoice, with flat billing and no month-end bill shock.
- After moving to self-hosted GLM 5.1 in April 2026, Revolut measured a 60% improvement in coding time and a 70% improvement in lead time across a 2,000-engineer sample.
- Tuning beat hardware: with the GPU count fixed at 56, time to first token fell from over 10 seconds to about 1.6 seconds while demand rose 76%.
- Frontier models (Codex, Claude Code, “Gemini Argan”) stay available but are treated as the exception, not the default.
- For an EU-regulated bank, the compliance recipe is human-in-the-loop coding tasks inside a sandbox with per-operation rules (allow grep, deny Gradle), data in equivalency-framework countries, zero data retention by default, and strong OpenTelemetry.
Key lessons
Section titled “Key lessons”- Measure AI impact on lead time, not only coding time. Revolut’s chart of 2,000 engineers showed the larger win from self-hosted GLM 5.1 was 70% on lead time versus 60% on coding time. The bottleneck for engineering is not coding; it is the surrounding work of digging through the inbox, Jira, and Confluence.
- Cheap tokens change behavior. Engineers were spending $1,000 to $10,000 a month on frontier APIs with weak ROI, so Revolut launched Claude Code at scale only under strict budget limits. At 30 cents per million tokens, engineers use AI guilt-free for mundane tasks instead of saving tokens for the end of the quarter.
- Size the fleet for latency, not throughput. Serving 2,000 engineers on GLM-4.3 takes roughly 56 B200 GPUs. Aim for sub-three-second time to first token; past five seconds, the Slack complaints start. Interactive throughput of 200 tokens per second is enough because engineers now run tasks in parallel and check in when done, and after 5 p.m. an engineer alone on the GPUs can get 800 TPS.
- Tune parameters before buying more GPUs. With the count fixed at 56, tuning moved throughput from about 3 requests per second to over 7 while cutting time to first token from over 10 seconds to about 1.6 seconds. That is an 88% performance improvement absorbing 76% more demand, all on the same hardware.
- Practical serving guidance from Revolut: treat million-token context windows as marketing (“long context is a scam”; 256K is what you really need), stay at FP4 on Blackwell-generation GPUs (the FP4-versus-FP8 gap is roughly a 40% difference in GPU footprint with zero loss in precision), consider TP8 over TP4 when KV cache is tight, and keep cache hit above 90% for coding workloads. Also evaluate speculative decoding, sequential prefill, and PD disaggregation.
- Route around a model’s gaps instead of waiting for one perfect model. GLM is text-only, so a local router (OpenCodex is one) sends image recognition to Gemini or “Luna” while GLM keeps the main task. The vision-capable GLM 5G Flash already pays off with Revolut’s UI designer, with a marked turnaround for UI product work.
- Keep endpoints OpenAI-compatible. All internal endpoints expose an OpenAI-compatible API with the Responses API, so the same self-hosted backend plugs into OpenCode, Claude, Codex, and the Codex app.
- Address the stigma of Chinese open-source models head-on for CIOs: you are not calling an inference endpoint in China. You take the weights and serve them on a US-based service. Classify coding tasks as human-in-the-loop rather than autonomous agents, and prove it with a sandbox that allows or denies individual operations (allow grep, not Gradle). That sandbox also shields against rogue internal actors and prompt injection. Keep data in countries inside the data-equivalency framework (US, EU, UK, Israel), require zero data retention from inference and GPU providers by default, and invest in strong OpenTelemetry so incidents can be investigated log-deep.
Watch this session
Section titled “Watch this session”Figures
Section titled “Figures”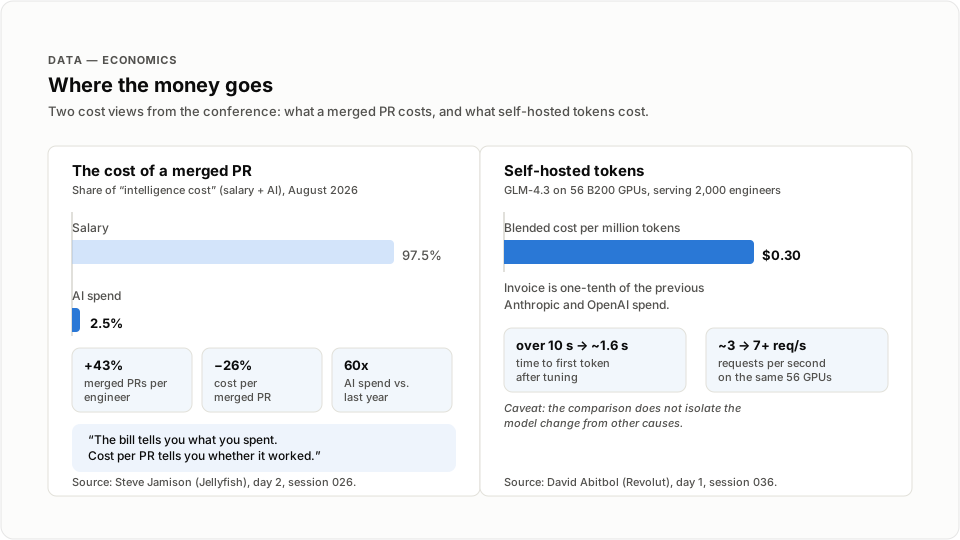
Token economics: the merged-PR split is day two’s Jellyfish talk; the self-hosted bar is this talk.
Notable quotes
Section titled “Notable quotes”- “First one, long context is a scam.” [06:10:58 | 2:58:49 PM]
- “As soon as you exceed five seconds, my Slack inbox starts to blow up, and so we know that’s the limit.” [06:08:35 | 2:56:26 PM]
- “In terms of cost, in terms of impact, self-hosting GLM, our blended cost of token is 30 cents per million, and so our invoice is one-tenth of what we were spending on.” [06:09:10 | 2:57:01 PM]
- “You’d be surprised what you find in a large company.” [06:14:34 | 3:02:25 PM]
Session narrative
Section titled “Session narrative”David Abitbol opened by introducing himself as the lead of AI operations at Revolut, warning the room that the talk would be technical. Since, in his words, this is the US and the audience may not know Revolut, he gave quick company facts: a digital bank in Europe with 80 million customers, live in 45 markets, the most downloaded financial app in Europe for the last year, and, as of July, Europe’s largest private company. He framed the company’s identity around shipping a lot of product, which drives its focus on engineering culture and excellence. He told the audience they had 50 minutes together; the streamed talk itself ran about 11 and a half minutes.
The core argument came with a chart of 2,000 engineers’ performance over the past year, plotting lead time in days and coding time in hours. He reset the timeline: Claude Code shipped around February 2025 on Sonnet 3.7, “the one that would delete your prod database,” far from today’s safer Claude and Codex. Revolut introduced AI in January 2025 with Gemini, the first time engineers could use private data with an AI, which produced a 10% improvement in lead time and 20% in coding time because people stopped reading Stack Overflow and documentation. Claude Code at scale showed little impact at the time, and with engineers spending a thousand to ten thousand dollars a month for unclear ROI, Revolut launched it under strict budget limits. The pivot came in April 2026 when the team began self-hosting open-source models on dedicated GPUs, with a stated preference for GLM for coding: GLM 5.1 delivered a 60% improvement in coding time and 70% in lead time. His takeaway: the engineering bottleneck is not coding but everything around it, and cheap tokens free engineers to delegate inbox, Jira, and Confluence drudgery without rationing.
The middle of the talk was a deep dive on serving economics and tuning. To serve 2,000 engineers, Revolut needs roughly 56 B200 GPUs hosting GLM-4.3, an 800-billion-parameter model. He shared empirical latency thresholds: aim for sub-three-second time to first token, because past five seconds his Slack inbox blows up, while throughput matters less since 200 tokens per second feels fine and after 5 p.m. an engineer can get 800 TPS to themselves. The blended cost is 30 cents per million tokens, making the invoice one-tenth of the old Anthropic and OpenAI spend, with flat billing and no bill shock. A second chart showed the same 56 GPUs going from about 3 requests per second with over-10-second first tokens in April to over 7 requests per second at about 1.6 seconds by August, an 88% performance improvement for 76% more demand. He then listed tuning parameters: context length (256K suffices), FP4 quantization on Blackwell hardware, tensor parallelism trade-offs between TP4 and TP8 for KV cache, cache hit above 90% for coding, plus speculative decoding, sequential prefill, and PD disaggregation.
He closed with production setup and a message “for the CIO in the room.” GLM is text-only, but the trade-off he would make every time is to take the smarter model and solve image recognition separately, using a local router such as OpenCodex to send vision work to Gemini or “Luna,” while GLM 5G Flash handles UI mockups well enough that Revolut’s UI designer already relies on it. All endpoints are OpenAI-compatible with the Responses API, so they drop into OpenCode, Claude, and Codex. On compliance, he argued there is no data-sharing problem in taking Chinese open-source weights and serving them on a US-based service rather than calling a China endpoint. As an EU-regulated bank under the strictest regime, Revolut treats coding tasks as non-autonomous, always with a human in the loop, guaranteed by a sandbox where operations are individually allowed or denied, for example grep yes, Gradle no. That sandbox also protects against rogue insiders (“You’d be surprised what you find in a large company”) and prompt injection, which he called less of a threat given how smart models have become but always a thing. Data privacy holds as long as data sits in countries within the data-equivalency framework (US, EU, UK, Israel), providers offer zero data retention by default, and a strong OpenTelemetry setup lets the team go deep into logs after any incident. He thanked the room and signed off.
Speaker details
Section titled “Speaker details”David Abitbol - Ops & Infrastructure Leader, Revolut. David is a strategy consultant specialized in financial services, passionate about tech, with a side hobby of statistical modelling. In this session he introduced himself as leading AI operations at Revolut, where he runs the internal AI coding stack. Links: LinkedIn, Twitter, Website
Result context: the reported token cost and lead-time improvement describe Revolut’s internal deployment. The comparison does not isolate the model change from other causes. Hosting and regulatory comments describe the speaker’s circumstances rather than a general compliance determination. See the official reading edition.
Full timestamped transcript
Section titled “Full timestamped transcript”[06:03:50 | 2:51:42 PM] All right.[06:03:51 | 2:51:43 PM] Hello, everyone.[06:03:52 | 2:51:44 PM] Welcome.[06:03:53 | 2:51:45 PM] My name is David.[06:03:54 | 2:51:46 PM] I lead AI operations at a company called Revolut.[06:04:02 | 2:51:54 PM] We have 50 minutes today together.[06:04:05 | 2:51:57 PM] We'll talk about high-performance engineering and self-hosting open-source model on the dedicated GPU.[06:04:12 | 2:52:03 PM] How does that sound?[06:04:13 | 2:52:04 PM] Cool.[06:04:14 | 2:52:05 PM] So it's going to be a technical one, so bear with me.[06:04:19 | 2:52:10 PM] So maybe to start off, because I know this is the US and you may not know Revolut, quick words about our company.[06:04:26 | 2:52:18 PM] We're a digital bank in Europe.[06:04:29 | 2:52:21 PM] We have 80 million customers.[06:04:31 | 2:52:23 PM] We're live in 45 markets with the most downloaded financial app in Europe for the last year.[06:04:39 | 2:52:31 PM] And as of July, we're Europe's largest private company.[06:04:45 | 2:52:37 PM] So we're doing okay.[06:04:48 | 2:52:39 PM] The emphasis of Revolut is, you know, shipping a lot of product, and so there's a high focus on engineering culture and excellence on that domain.[06:04:59 | 2:52:50 PM] And so we'll talk about that.[06:05:01 | 2:52:53 PM] So let's talk about some AI.[06:05:06 | 2:52:57 PM] We have a chart here.[06:05:06 | 2:52:58 PM] You're going to see two lines.[06:05:08 | 2:52:59 PM] This is a sample of 2,000 engineers' performance over the last year.[06:05:14 | 2:53:06 PM] So the green line is going to be lead time.[06:05:16 | 2:53:08 PM] So it's going to be when an engineer picks up a feature until a feature is merged and ready to be deployed.[06:05:24 | 2:53:16 PM] The blue line is going to be coding time.[06:05:26 | 2:53:17 PM] So the green line is in days.[06:05:27 | 2:53:19 PM] The blue line is in hours.[06:05:31 | 2:53:23 PM] Just to reset the timeline in case people forget, because AI moves really fast.[06:05:36 | 2:53:27 PM] Claude Code came out around February 2025, right?[06:05:40 | 2:53:31 PM] And that's the Claude Code Sonnet 3.[06:05:42 | 2:53:33 PM] 7, the one that would delete your prod database, right?[06:05:45 | 2:53:37 PM] Not the safe Claude and Codex that we have today.[06:05:48 | 2:53:40 PM] So bear in mind when we talk about adoption.[06:05:52 | 2:53:44 PM] So what you see on this chart is January 25, first introduced AI in the company, right?[06:05:59 | 2:53:50 PM] Gemini.[06:05:59 | 2:53:51 PM] First time people were able to use private data with an AI.[06:06:04 | 2:53:56 PM] Around February, we started playing around with Code, and then January is when we first launched Code at scale.[06:06:12 | 2:54:04 PM] What you see is Gemini had 10% improvement in lead time, 20% improvement in coding time, so that people no longer needed to look Stack Overflow and reading documentation.[06:06:24 | 2:54:15 PM] But then Code, not so much impact at the time.[06:06:28 | 2:54:19 PM] So when we launched it, we were highly skeptical about the cost of AI.[06:06:32 | 2:54:24 PM] We were seeing engineers spend a thousand a month, ten thousand a month, with not so much ROI.[06:06:38 | 2:54:29 PM] And so when we launched it, we launched it with strict budget limits.[06:06:43 | 2:54:35 PM] And so we're looking at the next thing, right?[06:06:44 | 2:54:36 PM] So how can we provide a limited token to our engineers so they can use AI guilt-free for a fraction of the cost?[06:06:51 | 2:54:42 PM] And so we looked into open source.[06:06:54 | 2:54:46 PM] So around April 26 is when we started self-hosting open source model, big fan of GLM for coding.[06:07:01 | 2:54:53 PM] So around that time, what you see, April 26, GLM 5.[06:07:06 | 2:54:58 PM] 1, we see 60% improvement in coding time, 70% improvement in lead time.[06:07:13 | 2:55:05 PM] So dramatic impact.[06:07:16 | 2:55:08 PM] What did we learn from this?[06:07:17 | 2:55:09 PM] Well, there's more impact on the lead time than on the coding time.[06:07:19 | 2:55:11 PM] So what we find is the bottleneck for engineering is not necessarily coding.[06:07:25 | 2:55:17 PM] You can save a lot of time not having to dig through your inbox or messing with Jira and Confluence.[06:07:31 | 2:55:22 PM] And so when you have a limited token.[06:07:33 | 2:55:24 PM] You're free to do that.[06:07:34 | 2:55:26 PM] You no longer have to save your tokens for the end of the quarter or the most difficult task.[06:07:42 | 2:55:34 PM] So where do we stand?[06:07:43 | 2:55:35 PM] Well, open source is now a priority.[06:07:46 | 2:55:38 PM] Our revoluts, unit economics are favorable.[06:07:49 | 2:55:41 PM] The billing is flat, we don't have any bill shock any of the month.[06:07:53 | 2:55:45 PM] And the frontier is the exception.[06:07:55 | 2:55:47 PM] So obviously, we keep using Codex, Claude Code.[06:07:58 | 2:55:50 PM] The latest model are fantastic.[06:08:00 | 2:55:51 PM] Gemini Argan, very good as well.[06:08:03 | 2:55:55 PM] But we keep them as exception.[06:08:08 | 2:55:59 PM] So how do we get there?[06:08:11 | 2:56:02 PM] Some metrics that matter when you're self-hosting model.[06:08:15 | 2:56:06 PM] So to serve 2,000 engineers, we roughly need 56 B200, and that's to host GLM-4.[06:08:21 | 2:56:13 PM] 3.[06:08:22 | 2:56:13 PM] GLM is a big model, right?[06:08:24 | 2:56:16 PM] 800 billion parameters.[06:08:27 | 2:56:19 PM] What you want to aim for is sub-three-second time to first token.[06:08:33 | 2:56:25 PM] This is empirical evidence.[06:08:35 | 2:56:26 PM] As soon as you exceed five seconds, my Slack inbox starts to blow up, and so we know that's the limit.[06:08:40 | 2:56:32 PM] In terms of throughput, doesn't really matter as much, right?[06:08:44 | 2:56:36 PM] So we serve, in terms of interactivity, 200 tokens per second.[06:08:49 | 2:56:40 PM] People are fine, you don't need to go higher.[06:08:52 | 2:56:43 PM] The way people work has changed.[06:08:53 | 2:56:44 PM] We no longer look at the stream of thinking tokens.[06:08:56 | 2:56:48 PM] People run tasks in parallel and check in when the task is done.[06:09:00 | 2:56:52 PM] But if you want to have high throughput and you're an engineer at Revolut, you just connect after 5 p.[06:09:04 | 2:56:56 PM] m.[06:09:04 | 2:56:56 PM] when no one is on GPU, and you can get 800 TPS, and then, you know, it's a dream.[06:09:10 | 2:57:01 PM] In terms of cost, in terms of impact, self-hosting GLM, our blended cost of token is 30 cents per million, and so our invoice is one-tenth of what we were spending on.[06:09:27 | 2:57:18 PM] Anthropic and OpenAI.[06:09:29 | 2:57:20 PM] So there's a lot of tuning that goes into running open source models.[06:09:34 | 2:57:26 PM] If you just get GPUs and upload weights on a GPU and you start doing some inference, you're going to get terrible performance.[06:09:43 | 2:57:35 PM] It's because your workload is going to be very dependent on the parameters that you set.[06:09:50 | 2:57:42 PM] So if you look all the way to the left of that chart, the blue line is going to be demand, so that's requests per second.[06:09:56 | 2:57:47 PM] That's going to be what's going to be the bottleneck for your latency.[06:09:58 | 2:57:49 PM] For your latency for your GPUs.[06:10:01 | 2:57:52 PM] And the red line is what we're optimizing for.[06:10:02 | 2:57:54 PM] That's the time to first token.[06:10:05 | 2:57:57 PM] So when we started back in April, you could see requests per second around three, which is high but not so high, and time to first token over 10 seconds, which is very slow.[06:10:19 | 2:58:10 PM] A lot of the data that you see is the same number of GPU.[06:10:22 | 2:58:13 PM] We didn't increase GPU count; we stayed at 56.[06:10:25 | 2:58:17 PM] And by the end, you see in August, requests per second were about over seven and time to first token were around 1.[06:10:32 | 2:58:23 PM] 6.[06:10:32 | 2:58:24 PM] So we've had 88% improvement in performance for 76% increased demand.[06:10:39 | 2:58:31 PM] So the learning from this is there's a lot of parameters that you can improve on, and you really need to rescale if you're looking to serve a model.[06:10:49 | 2:58:41 PM] So let's talk parameters.[06:10:52 | 2:58:43 PM] There's no secret recipe, but the things you should consider are the following.[06:10:58 | 2:58:49 PM] First one, long context is a scam.[06:11:01 | 2:58:53 PM] You really need to be mindful that even though you can serve 1 million token, 256, 256 is really what you need.[06:11:10 | 2:59:01 PM] Quantization: if you're running Blackwell generation GPU, you don't want to run anything higher than FP4, and if FP4 is best, roughly going from FP4 to FP8 is a 40% saving in GPU footprint for zero loss in precision.[06:11:29 | 2:59:20 PM] Other parameters to consider: tensor parallelism.[06:11:31 | 2:59:22 PM] Even though GLM fits on TP4, you don't have enough KV cache, and so maybe a TP8 works better depending on how large your workload is.[06:11:40 | 2:59:32 PM] And then on the more esoteric, check your cache hit.[06:11:44 | 2:59:35 PM] Coding tasks need to be above 90% cache hit.[06:11:48 | 2:59:40 PM] And you can look into optimize spec decoding, sequential prefill, PDDAG, all of these.[06:11:57 | 2:59:49 PM] Cool.[06:11:58 | 2:59:49 PM] So now let's talk about production setup.[06:12:01 | 2:59:53 PM] GLM obviously is a text-only model, which is a limitation for some people.[06:12:07 | 2:59:58 PM] The trade-off, I would say, we would make every time is get the smarter model and figure out how to do image recognition another way.[06:12:14 | 3:00:05 PM] You can easily have a local router, OpenCodex is one, where you would route any image recognition to Gemini or Luna and keep GLM for the main task.[06:12:26 | 3:00:17 PM] If you really need some vision model, GLM 5G Flash works really well.[06:12:32 | 3:00:23 PM] We have our UI designer making great use of it.[06:12:37 | 3:00:29 PM] Turnaround for UI product has gone a really, really long way.[06:12:44 | 3:00:35 PM] And then the last one is going to be about the harness.[06:12:48 | 3:00:40 PM] So all of these endpoints are going to be OpenAI-compatible API with response API, and so you can use them inside OpenCode, Claude, Codex, Codex app as well.[06:13:00 | 3:00:51 PM] Works really well.[06:13:00 | 3:00:52 PM] And so that's what we recommend.[06:13:07 | 3:00:59 PM] And then last message, this one is for the CIO in the room.[06:13:13 | 3:01:04 PM] There's been a lot of stigma in using Chinese open-source model.[06:13:18 | 3:01:10 PM] So the simple consider is you're not using the inference dedicated endpoint that goes to China.[06:13:24 | 3:01:15 PM] You're just getting the weights and putting them on a U.[06:13:27 | 3:01:19 PM] S.[06:13:28 | 3:01:19 PM] -based service.[06:13:29 | 3:01:20 PM] So for data sharing side, this is totally fine.[06:13:34 | 3:01:26 PM] Revolut in particular, because we're an EU-regulated bank, we fall under the most strict regime in terms of compliance.[06:13:43 | 3:01:35 PM] And so what we find that works is all of these coding tasks are not considered autonomous agents.[06:13:51 | 3:01:42 PM] They're always with a human in the loop.[06:13:53 | 3:01:44 PM] And so how do you give reassurance that you have a human in the loop?[06:13:57 | 3:01:49 PM] You start by creating a sandbox that guarantees that.[06:14:01 | 3:01:52 PM] And the sandbox means now if you've used Codex Cloud Code, it has all of these features of approve for me.[06:14:07 | 3:01:58 PM] You just have to set the rules for the operations that you don't want to allow.[06:14:10 | 3:02:02 PM] So you can allow grep, but not Gradle, for instance, and that's going to give confidence to your regulator that this is not an autonomous agent that needs different supervision.[06:14:23 | 3:02:14 PM] The sandbox also protects you from rogue use, right?[06:14:25 | 3:02:17 PM] You may have bad actor inside your company and you want a shield for that.[06:14:30 | 3:02:21 PM] You'd be surprised what you find in a large company.[06:14:34 | 3:02:25 PM] And then the last one is prompt injection.[06:14:36 | 3:02:27 PM] Not so much a thing now, given how smart models are, but always a thing.[06:14:42 | 3:02:33 PM] In terms of data privacy, we spoke about it.[06:14:44 | 3:02:35 PM] So as long as the data sits in one of the countries that are in the data equivalency framework, so US, EU, UK, Israel, you're fine.[06:14:53 | 3:02:44 PM] You can get GDPR there.[06:14:55 | 3:02:46 PM] All of your inference provider or GPU provider are going to have zero data retention by default.[06:15:03 | 3:02:54 PM] And then the last thing you need is a very strong open telemetry so that if you ever have an incident, you need to be able to go deep and look at the logs.[06:15:15 | 3:03:06 PM] Also gives you some analytics.[06:15:21 | 3:03:12 PM] All right.[06:15:21 | 3:03:13 PM] Thanks, everyone.[06:15:22 | 3:03:13 PM] That was all for my talk.